A portable snapshot
Changes are committed to a checksummed WAL. Call checkpoint() before copying the .rvec snapshot on its own, with writes paused; otherwise preserve the matching snapshot and WAL together.
Recern Vector 0.4.0 combines embedded vector storage with a single-node HTTP server and portable Python, Rust and Node.js clients for Recern and Qdrant.
pip install recern-vectorRelease notes, v0.4.0 Recern Workspace · demo database
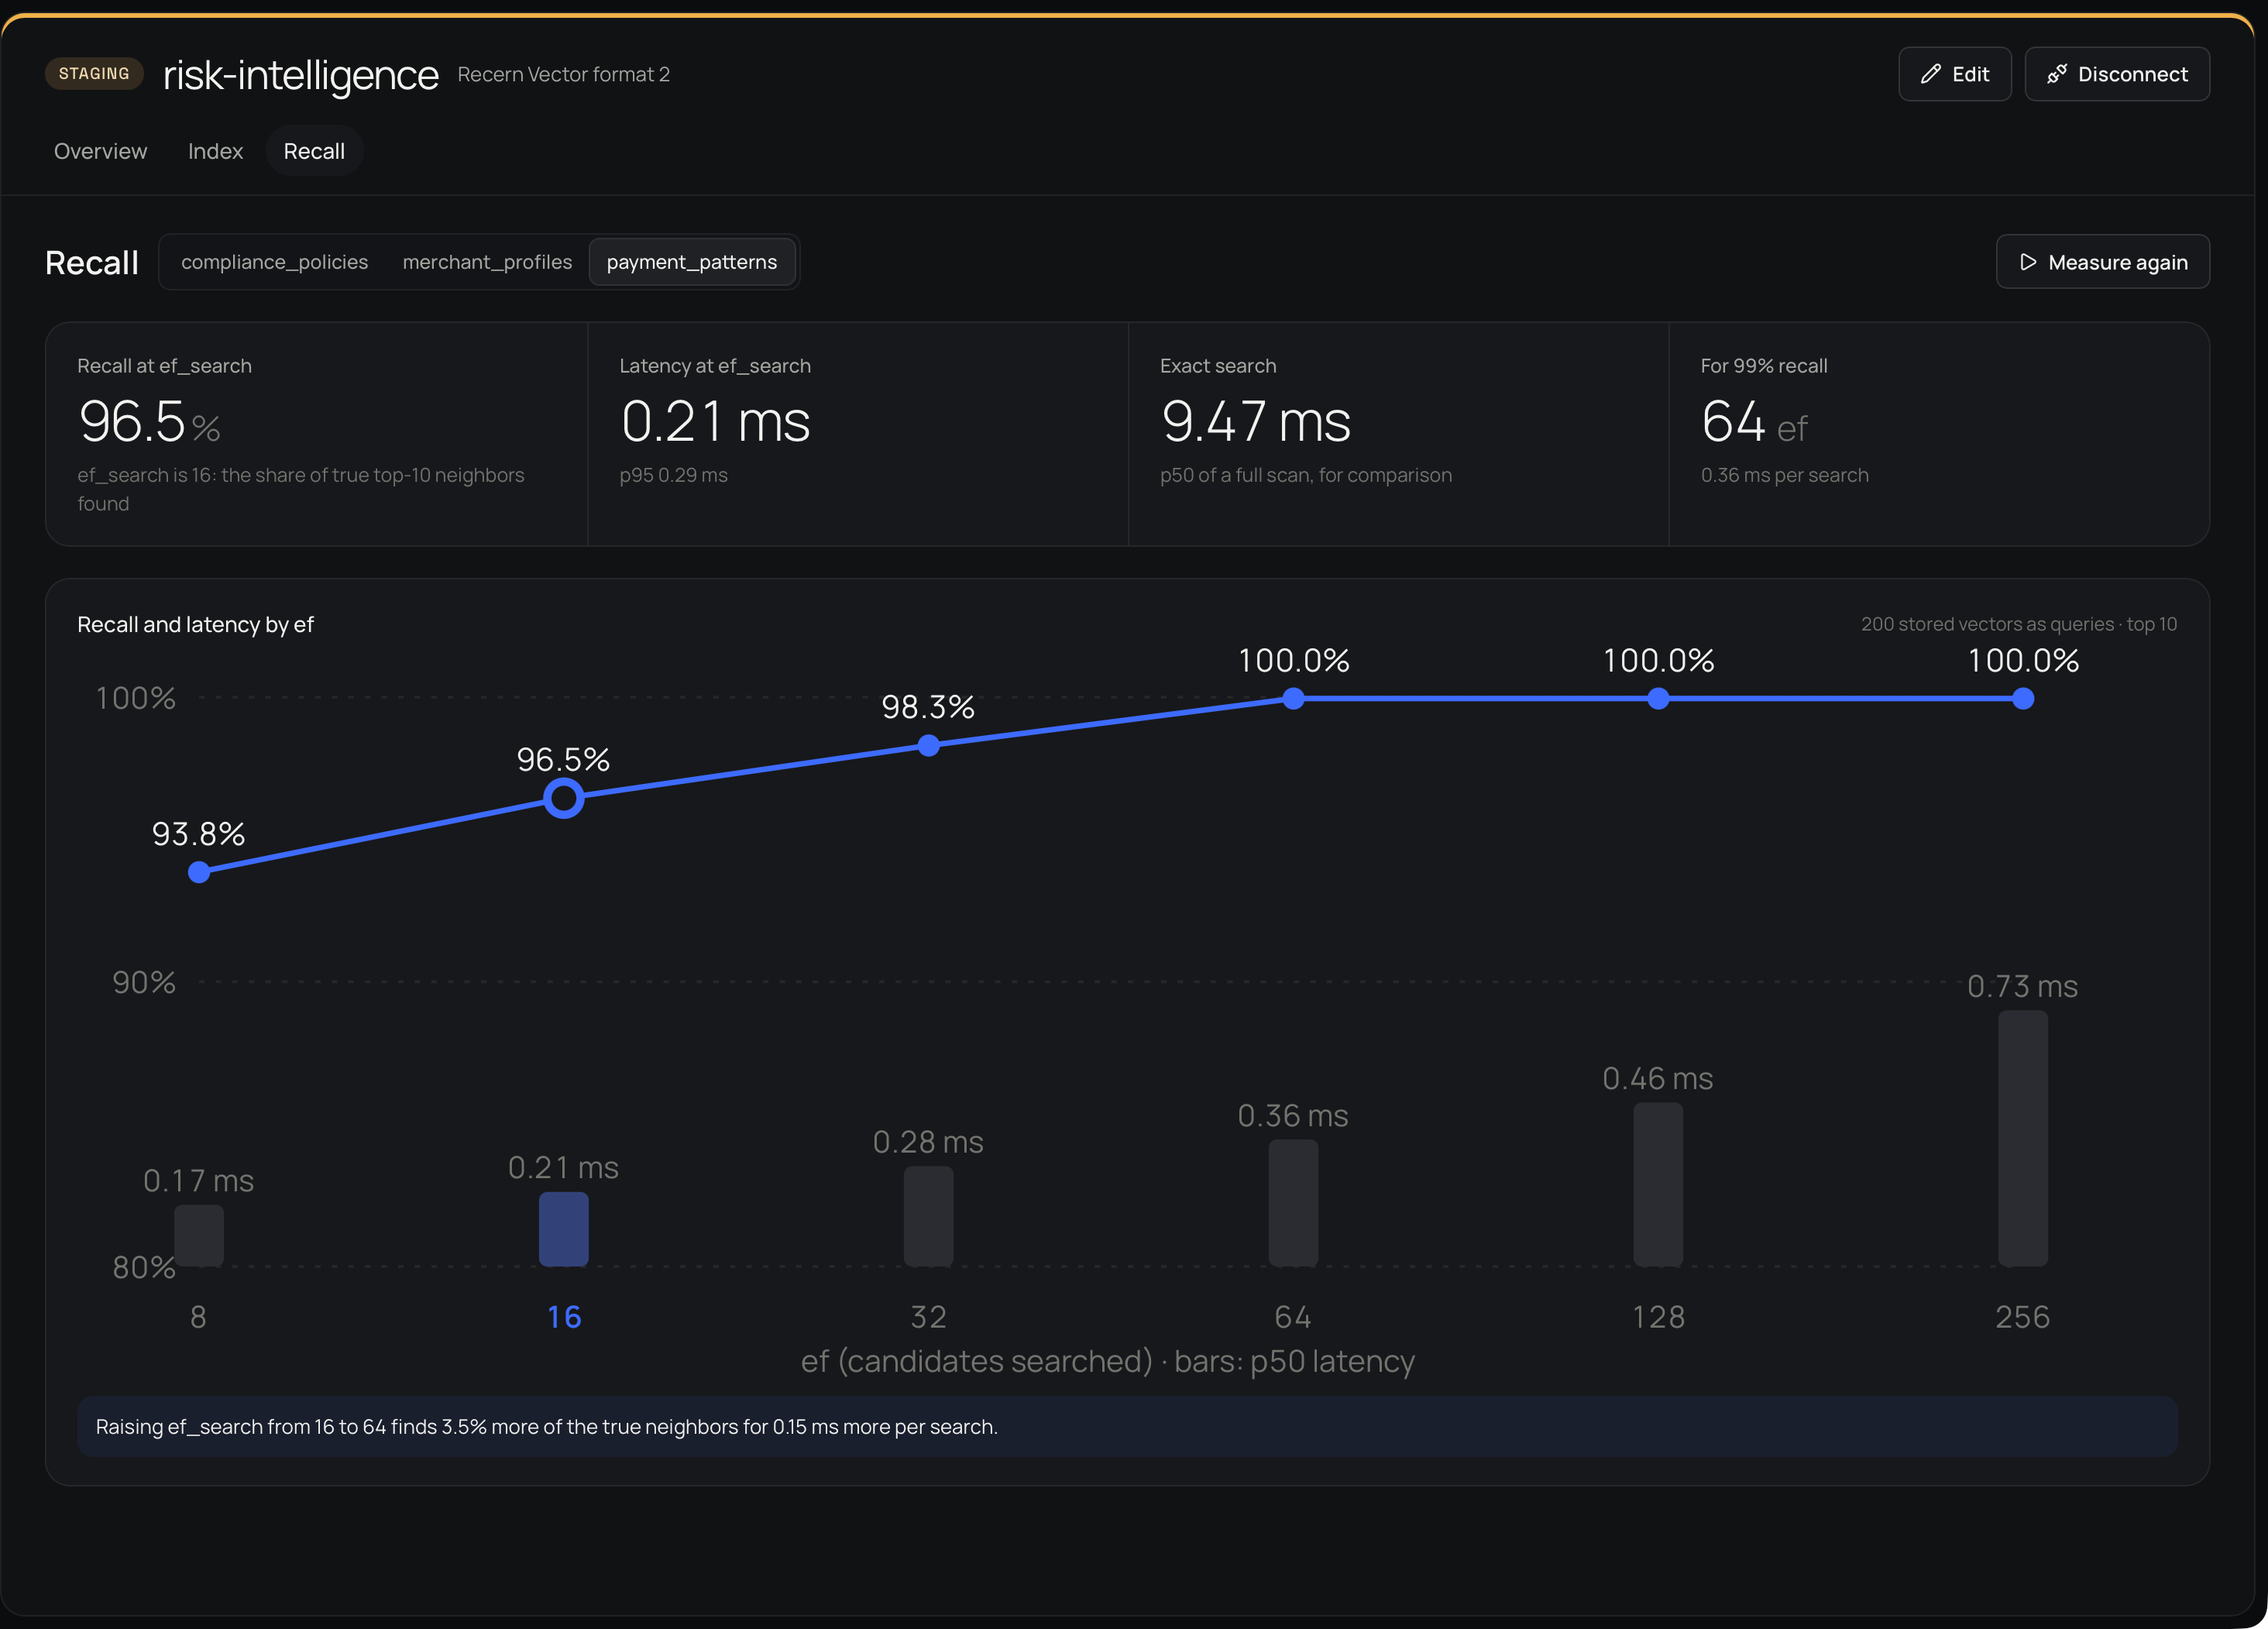
Measure recall and latency at different ef values on the payment_patterns int8 collection.
Recern Vector 0.4.0 · 2026-11-02 · embedded f32 and int8; HTTP and Qdrant are outside this measurement.
queries/s on SIFT1M at recall ≥ 0.95
queries/s on GloVe-100 at recall ≥ 0.95
to build the SIFT1M f32 index · 4 threads
p95 query latency on SIFT1M at recall ≥ 0.95
Changes are committed to a checksummed WAL. Call checkpoint() before copying the .rvec snapshot on its own, with writes paused; otherwise preserve the matching snapshot and WAL together.
Run inside your application or use the authenticated single-node HTTP server. Portable clients keep the same data operations across embedded Recern, Recern HTTP and Qdrant.
Any search can report its strategy, the nodes it visited, how selective the filter was and how long it took. Stats show the graph layers, memory use and any records a search cannot reach, and recall can be measured on your own data.
The same database from Python and from the command line. The output on the right is a real run on 20,000 records with a metadata filter.
import recern_vector as rv

db = rv.Database.open_or_create("docs.rvec")
docs = db.create_collection("docs", dim=384, metric="cosine")
docs.upsert_many(ids, embeddings, metadatas)

hits = docs.search(query, k=5, filter={"lang": "en"})
docs.explain(query, k=5) # strategy, visited nodes, time$ recern-vector query docs.rvec docs --like doc-42 -k 3 \
--filter '{"lang": "en", "year": {"$gte": 2020}}' \
--explain
# id distance metadata
1 doc-42 -0.00000 {"lang":"en","year":2024}
2 doc-18861 0.63155 {"lang":"en","year":2022}
3 doc-10899 0.63834 {"lang":"en","year":2024}
strategy hnsw
ef 64
selectivity ~19.9% of records match the filter
visited 7,244 nodes
distances 7,330 computed
time 529 µsPython bindings take NumPy float32 arrays without converting each element. Batch inserts build the index on all cores.
Use the same collection, record and filtered-search operations on embedded Recern, Recern HTTP and Qdrant. Profile v1 preserves logical IDs, metadata precision, distance semantics and explicit backend capabilities.
Export a consistent snapshot from embedded Recern or Recern HTTP and import into new Recern or Qdrant collections. Includes checksums, dry-run, resume and read-back verification. Int8 exports contain stored, dequantized vectors.
A graph index with per-collection m, ef_construction and ef_search, and an exact scan when you need ground truth.
Each collection has a fixed dimension and metric. Cosine vectors are normalized when they are stored.
Equality, $in, ranges and nested $and, $or and $not. A cost planner samples filter selectivity, chooses exact or HNSW search and adapts the search effort.
Embedded Recern builds batch indexes on all cores and rejects an invalid batch before writing. Qdrant batches do not carry an atomicity guarantee.
Replace or delete records by id, then compact to rebuild the collection without deleted records.
stats(), explain() and estimate_recall() are part of the API, not a separate tool.
A PyO3 wheel for CPython 3.11 and later, with type hints.
init, create-collection, insert, query, inspect, recall, checkpoint and compact.
Versioned files, checksums and golden compatibility tests, with existing format-1 snapshots still readable.
save() commits changed pages to the WAL; checkpoint() writes a self-contained snapshot. Interrupted trailing records are ignored during recovery.
Per-collection int8 codes with per-vector scales. Measure recall on your data to choose the storage and accuracy tradeoff.
Node-API 8, TypeScript and portable async operations on native workers. Verified npm tarballs for Linux x64/ARM64, macOS Intel/Apple silicon and Windows x64 are in the GitHub release.
Apple M3 Max · 36 GB · 2026-11-02
Recern Vector 0.4.0 · 2026-11-02 · embedded f32 and int8; HTTP and Qdrant are outside this measurement.
| Engine | SIFT1M · recall ≥ 0.95 | GloVe-100 · recall ≥ 0.95 |
|---|---|---|
| Recern Vector 0.4.0 · f32HNSW · 0.4.0 | 7,712queries/s · ef=80 | 618queries/s · ef=1280 |
| Recern Vector 0.4.0 · int8HNSW · 0.4.0 | 3,565queries/s · ef=80 | 246queries/s · ef=1280 |
| faiss HNSW · f32HNSW · 1.15.1 | 6,605queries/s · ef=80 | 356queries/s · ef=1280 |
Embedded data must fit in memory; saves still encode the full image. Migration requires an immutable export and exclusive access to new destination collections. Consistent Qdrant export is not supported. Clustering and a hosted service are outside the 1.0 scope.
Workspace inspects pgvector columns and indexes, Redis search indexes and vector sets when the server supports them, and Recern Vector snapshots with committed WAL changes. Recall checks are available for Recern Vector collections, including f32 and int8.
Explore the workspace